Cycling through all six. Tap any point to stop.
Measured on six things
Structured Amazon product, search and category data through a REST API.
Security
52HTTPS and HSTS enforced with X-Content-Type-Options and SPF in place, but no CSP, frame protection, Referrer-Policy or DMARC, and no SOC 2/ISO page surfaced. SSO and audit logs are Enterprise-only.
Screenshots
1 / 1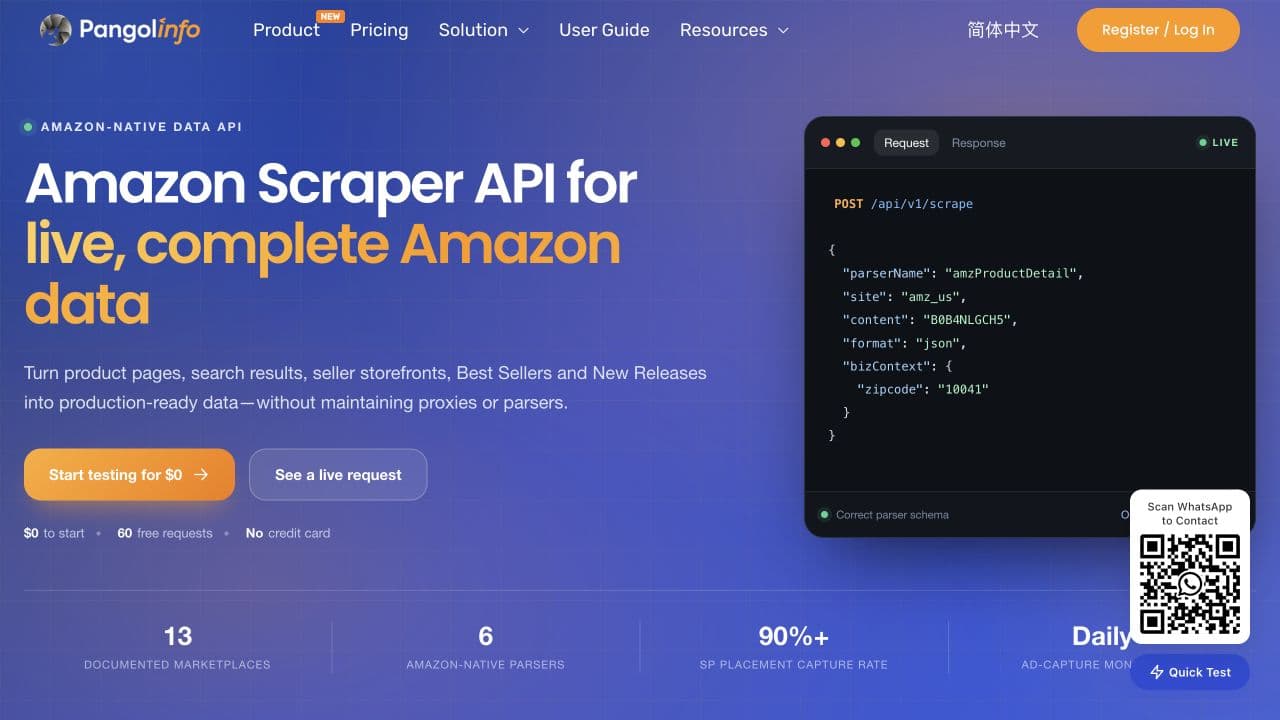
About this app
Pangolinfo Amazon Scraper API provides structured Amazon product, keyword search, category, seller, Best Sellers and New Releases data for e-commerce research and developer workflows. Requests support marketplace and delivery-location context, with JSON, HTML or Markdown output options. Teams can use the data for catalog analysis, product research and monitoring workflows. Access requires a Pangolinfo API key. Limited trial access is available; ongoing data collection uses paid API credits. Product reviews are provided through a separate API rather than this product endpoint. Documentation: https://docs.pangolinfo.com/en-api-reference/amazonApi/amazonScrapeAPI
Key features
- 1Six Amazon-native parsers: product detail, keyword search, category, seller, Best Sellers, New Releases
- 2Sponsored-vs-organic position capture with marketplace and delivery-ZIP context across 13 marketplaces
- 3JSON, HTML or Markdown output with per-parser credit pricing and a usage calculator
- 4Interactive request builder with cURL/Python/Node tabs and 60 free credits, no card required
Target customer profile
Drawn from the product itself, not from a survey.
Demographic
E-commerce developers and SaaS builders needing Amazon data in their backend
Pain points
Maintaining proxies, rendering, retries, and parser drift from Amazon layout changes
Primary needs
A stable REST endpoint that returns reliable, structured Amazon JSON on demand
Demographic
Amazon sellers and product researchers comparing niches and category density
Pain points
Manually checking BSR, price bands, and new-product momentum across categories
Primary needs
Fresh product, category, Best Seller, and New Release data for inventory decisions
Demographic
PPC and keyword analysts tracking paid vs. organic search placements
Pain points
Sponsored placements get missed, muddying ad attribution and rank tracking
Primary needs
Position-level sponsored vs. organic evidence with marketplace and ZIP context
Demographic
Data teams and AI agent developers grounding tools in live marketplace evidence
Pain points
Stale datasets and generic scraping schemas that need heavy cleanup
Primary needs
Consistent, Amazon-native fields delivered via API or callback pipelines
Scout Review
Written by AI from measured evidence, scored out of 100.
Pangolinfo Amazon Scraper API is a focused, developer-first Amazon data product with a genuinely useful wedge: Amazon-native parsers that return structured fields (ASIN, BSR, sponsored placement, seller, variations) instead of generic HTML. The marketing site is fast (94 mobile / 100 desktop Lighthouse) and the onboarding is clean — 60 free credits, no card, an interactive request builder. Pricing is usage-based with a calculator that prices each parser per page. The gaps are polish and trust: an empty gradient hero, a thin security header set with no published compliance, and accessibility failures on contrast and heading order. It's a competent indie tool with a real niche, not yet a category leader.
Measure by measure
Usability
68Clear 3-step path from signup to first request, 60 free credits with no card, an interactive request builder with cURL/Python/Node tabs, and a pricing calculator that prices each parser. Solid onboarding for a dev tool.
Design
58Clean developer-marketing look with a real request/response code window and punchy orange CTAs, but the hero is a tall empty gradient that buries the headline near the fold and the QR code placement feels arbitrary.
Speed
79Lighthouse mobile 94/100 (LCP 1.8s, TBT 0ms) and desktop 100/100. CLS 0.12 is the only blemish — a small layout shift, but the page itself is genuinely snappy.
Security
52HTTPS and HSTS enforced with X-Content-Type-Options and SPF in place, but no CSP, frame protection, Referrer-Policy or DMARC, and no SOC 2/ISO page surfaced. SSO and audit logs are Enterprise-only.
Accessibility
68Lighthouse a11y 91/100 with a Chinese language toggle and responsive layout, but three real failures: ARIA roles missing required children, insufficient color contrast, and non-sequential heading order. No WCAG statement found.
Growth
62A real, specific wedge: Amazon-native parsers with sponsored-vs-organic position capture and ZIP/marketplace context, aimed at devs who'd otherwise fight generic scrapers. Differentiated, but the category is crowded.
Improvement areas
- Security posture: no CSP, frame protection, Referrer-Policy or DMARC; no SOC 2/ISO page; SSO gated to Enterprise
- Accessibility: three Lighthouse failures (ARIA role children, color contrast, heading order) and no WCAG statement
- Design: tall empty gradient hero buries headline and CTAs; QR code placement is arbitrary
- Trust signals: only a Twitter profile listed; no public case studies, reviews or compliance documentation
Design & Usability
The homepage is a competent developer-marketing page: a realistic POST /api/v1/scrape code window in the hero, orange CTAs that promise '$0 to start', and a compact stats row (13 marketplaces, 6 parsers, 90%+ SP capture). The interactive request builder with cURL/Python/Node tabs is the best part — it lets you see the exact request shape before signing up. Onboarding is a clean three steps: create account, copy key, run 60 free requests. The weaknesses are cosmetic but real: a tall, textureless gradient hero that pushes the headline and CTAs into the bottom third, an arbitrarily placed QR code, and small nav text. It reads as a solid indie dev tool, not a polished enterprise product.
Speed & Security
Speed is the standout: Lighthouse mobile 94/100 with LCP 1.8s and TBT 0ms, desktop a perfect 100/100. The only blemish is a 0.12 CLS shift. Security is the weak spot — HTTPS and HSTS are enforced and X-Content-Type-Options and SPF are present, but there's no CSP, no frame protection, no Referrer-Policy, and no DMARC. The probe scored 6/12 checklist points. No SOC 2, ISO, or bug bounty page surfaced, and SSO plus audit logs are gated behind Enterprise. For a product that handles API keys and scraped marketplace data, that's a thin public security posture — not broken, but not reassuring either.
Accessibility & Growth
Accessibility lands at 91/100 on Lighthouse with a Chinese language toggle and responsive layout, but three concrete failures remain: ARIA roles missing required children, insufficient color contrast, and non-sequential heading order. No WCAG statement is published. Growth is the more interesting story: Pangolinfo's wedge is Amazon-native parsing — six parsers covering product detail, keyword search with sponsored-vs-organic positions, category, seller, Best Sellers and New Releases, with marketplace and ZIP context across 13 marketplaces. That's a real differentiator against generic scrapers like ScraperAPI, Bright Data and Oxylabs, which sell raw page fetch and leave the Amazon schema to you. The category is crowded and the incumbents have scale, but the specificity of the pitch gives it a plausible lane.
Conclusion
If you're building an Amazon data pipeline and you're tired of writing parser maintenance for every layout change, Pangolinfo is worth the 60 free requests to test. The Amazon-native schema is the actual product here — the sponsored-vs-organic position capture and ZIP context are the kind of fields generic scrapers make you reconstruct by hand. Go in with eyes open on the security side: no SOC 2, no CSP, SSO gated to Enterprise. For a solo dev or small team that's fine; for a compliance-sensitive buyer, ask sales for the details before you commit credits.
Suggestions for improvement
- Publish a security page with SOC 2 status, data retention policy, and a bug bounty or disclosure contact — the current header set is thin.
- Add CSP, frame protection, Referrer-Policy and DMARC; these are cheap wins that would move the security score materially.
- Fix the three Lighthouse a11y failures: ARIA role children, color contrast on the orange CTAs, and heading order.
- Tighten the hero: reduce gradient height, move headline and CTAs above the fold, and either integrate or remove the QR code.
Alternatives comparison
Named competitors, point by point. Nobody paid to appear here or to be left out.
 Pangolinfo Amazon Scraper API |  ScraperAPI |  Bright Data |  Oxylabs | |
|---|---|---|---|---|
| Amazon-native structured parsers (product, keyword, category, seller, BSR, New Releases) | Yes — 6 dedicated Amazon parsers returning ASIN, BSR, variations, seller fields | No — generic page fetch; Amazon structure must be parsed by the customer | Partial — has Amazon dataset offerings but sold as datasets, not a per-request parser API | Partial — Amazon scraper API exists but schema is less Amazon-native per parser |
| Sponsored vs. organic placement capture with ZIP/marketplace context | Yes — position, page, sponsored flag, badge, ZIP context across 13 marketplaces | No — returns raw HTML; sponsored detection is on the customer | No — dataset-level, not position-level sponsored evidence per request | No — generic Amazon scraper output, no sponsored-placement field |
| Free trial / entry pricing | 60 free credits/mo, no card; Starter $19 for 9.6k credits | Free tier with limited requests; paid plans from ~$49/mo | Free trial credits; usage-based pricing, higher entry cost | Free trial available; paid plans from ~$49/mo |
| Published compliance / security certifications | None surfaced; HTTPS+HSTS only; SSO and audit logs Enterprise-only | SOC 2 and GDPR documentation published | SOC 2, ISO 27001, GDPR compliance pages published | ISO 27001, SOC 2, GDPR compliance published |
| Output format flexibility | JSON (1 credit), HTML or Markdown (0.75 credits) | HTML/JSON via render flag; no Markdown | JSON, CSV, HTML depending on dataset | JSON and HTML; no Markdown |
ScraperAPI
Another web-data service to evaluate against your own technical requirements and pricing needs.
Bright Data
Another web-data service to evaluate against your own technical requirements and pricing needs.
Oxylabs
Another web-data service to evaluate against your own technical requirements and pricing needs.
Comparing options? See Pangolinfo Amazon Scraper API alternatives, scored side by side
More Development & Engineering apps
View all Development & Engineering
CreateMyCoin
92A no-code Solana token creator that deploys SPL tokens in...

Vibe Coding Agent Skills
92A free, open-source platform offering 110 AI agent skills...

CC Switch
91Open-source desktop app for switching AI coding providers...

TaxID
90Fast EU VAT validation API for developers, covering 27 EU...

BeartIMAGE
88BeartIMAGE is a free, web-based image processing platform engineered for fast, bulk photo editing and conversion directly in your browser.

Claw Messenger
88Claw Messenger is an iMessage API service that gives AI a...

DataHabibi
88AI-powered Dubai real estate data platform with 12M+ DLD ...

ButterKit
82macOS app for App Store screenshots: 3D mockups, auto-tra...

PERM Processing Time: Current DOL Queue & History
88PERM Processing Time is an independent data analysis platform that helps users navigate the U.S. Department of Labor’s permanent labor certification process.

StockFit API
87A developer-first financial data API providing structured...

ProcessSpy
87A native macOS process explorer and advanced monitor that...

Credyt
87Real-time monetization infrastructure for AI products tha...
A platform dedicated to providing unbiased reviews of newly launched applications, analyzing everything from their features to their full potential.
info@scoutforge.net© 2026 Scoutforge. All rights reserved.