Cycling through all six. Tap any point to stop.
Measured on six things
Seed Audio 1.0 - Zero-Shot Multimodal Audio Generator
Growth
42ByteDance-backed June 2026 launch with quick review coverage. Third-party access only, minimal community footprint, early credit-based distribution.
Screenshots
1 / 1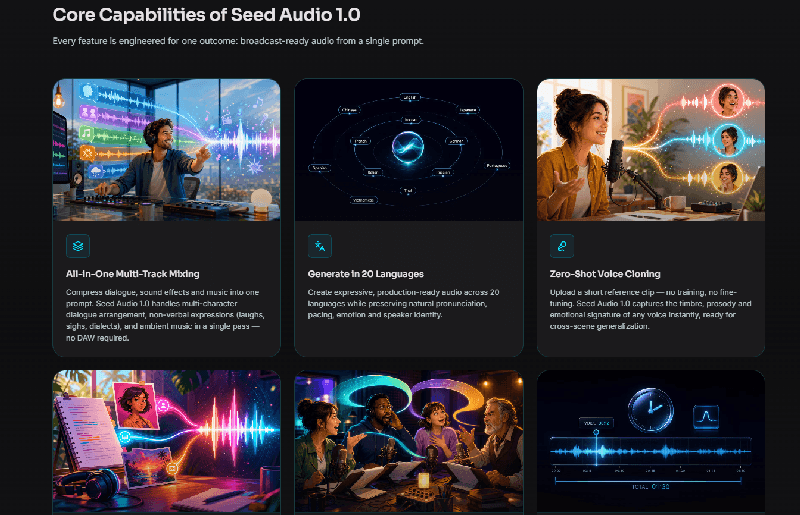
About this app
Create cinematic dialogue, sound effects, music and ambience from one prompt with Seed Audio 1.0, a zero-shot multimodal AI audio generation model online.
Key features
- 1All-in-one generation of dialogue, sound effects, music and ambience from one prompt
- 2Zero-shot multi-character voice consistency up to 8 speakers with continuation mode
- 3Multi-modal input: text, reference audio, and image for style and character definition
Target customer profile
Drawn from the product itself, not from a survey.
Demographic
Podcasters and audio content creators
Pain points
Need to produce high-quality, multi-host podcasts quickly without manual editing or hiring voice actors
Primary needs
All-in-one audio generation that handles dialogue, music, and effects seamlessly
Demographic
Independent filmmakers and YouTubers
Pain points
Limited budget and time for professional sound design, dubbing, or foley work
Primary needs
Fast, affordable tool to generate cinematic audio and voiceovers from text
Demographic
Marketing and advertising professionals
Pain points
Producing brand audio spots requires studio booking, voice casting, and post-production
Primary needs
Instant generation of ad-ready audio with emotional pacing and brand consistency
Scout Review
Written by AI from measured evidence, scored out of 100.
Seed Audio 1.0 stands out for delivering true all-in-one cinematic audio from a single prompt, a genuine technical step beyond standard TTS or music generators. The site and pricing model are straightforward, and early reviews confirm impressive multi-speaker and effects mixing quality. Limitations around length, language coverage, and access keep it from feeling fully mature, but the core capability is already production-relevant for short-form creators.
Measure by measure
Usability
62Clear templates, prompt controls, and tiered one-time plans. Credit metering and beta CTA keep onboarding simple but limit discoverability of advanced features.
Design
70Coherent dark theme with neon waveforms and disciplined 3-column grid. Hero copy is dense and cards repeat visual patterns, but overall polish stands out for an early AI demo.
Speed
70Mobile Lighthouse 76/100 with solid CLS and TBT. No user lag complaints in early reviews; lightweight visuals help perceived speed.
Security
50HTTPS + HSTS in place. Missing CSP, DMARC, and any public compliance docs. ByteDance infrastructure provides indirect trust.
Accessibility
5587 Lighthouse score undermined by missing ARIA names and contrast issues. No a11y statement; 20-language claim is the strongest signal.
Growth
42ByteDance-backed June 2026 launch with quick review coverage. Third-party access only, minimal community footprint, early credit-based distribution.
Improvement areas
- Max generation length capped at 2 minutes per pass with credit metering
- Limited to English and Chinese in current documentation; no public SOC 2 or a11y statement
- Access primarily through third-party gateways rather than direct self-serve
Design & Usability
Seed Audio 1.0 presents a polished dark interface with consistent neon waveform branding and a clean 3-column capabilities grid that feels modern for an AI audio tool. The hero uses bold typography effectively, though dense body copy reduces scannability. Usability benefits from visible templates, a straightforward generator with pitch/speed controls, and transparent one-time pricing tiers that avoid subscriptions. The single prominent beta CTA simplifies entry, but deeper navigation and feature discoverability remain limited on the homepage. Overall the experience is competent and creator-friendly for short-form work.
Speed & Security
Performance lands solidly with a 76/100 mobile Lighthouse score driven by excellent CLS and low TBT, though LCP at 6.2 seconds leaves room for optimization. No widespread lag reports appear in early coverage. Security is baseline: HTTPS and HSTS are enforced with an SPF record, but the absence of CSP, DMARC, and any published audits or compliance certifications keeps it in the middle of the pack for a ByteDance-backed product. The combination supports a functional early-stage service without raising red flags.
Accessibility & Growth
Accessibility scores 55 after automated checks reveal missing ARIA labels on inputs and buttons plus contrast shortfalls, despite an 87 Lighthouse number. No dedicated accessibility documentation exists. Growth is modest for a June 2026 launch: strong ByteDance pedigree and rapid third-party coverage exist, yet direct access remains limited, community signals are thin, and the product is still distributed primarily through gateways rather than broad self-serve adoption.
Conclusion
For podcasters, YouTubers, and indie filmmakers needing fast dialogue-plus-effects without a full studio, Seed Audio 1.0 is worth testing through available gateways today. The one-time credit model and clear feature tiers make experimentation low-risk while the underlying model continues to improve.
Suggestions for improvement
- Add keyboard navigation testing and fix ARIA/button naming to lift accessibility above the current band.
- Publish a lightweight security page or compliance summary to move security past baseline.
- Expand direct self-serve access and add a public changelog to accelerate visible growth signals.
Alternatives comparison
Named competitors, point by point. Nobody paid to appear here or to be left out.
 Seed Audio 1.0 |  ElevenLabs |  Suno |  Descript | |
|---|---|---|---|---|
| All-in-one multi-track generation (dialogue + SFX + music) | Yes - single prompt outputs fully mixed scene | No - voice cloning and TTS only | No - music generation focused | Partial - AI features require manual multi-track assembly |
| Multi-character dialogue with consistent voices | Yes - up to 8 characters, zero-shot cloning | Yes - strong voice cloning and multi-speaker | No - primarily single-track music | Yes - studio features for multi-speaker editing |
| Sound effects and ambience generation | Yes - included in single-pass output | No - voice-focused only | Limited - music and basic stems | Partial - stock libraries and manual placement |
ElevenLabs
Focuses on voice cloning and TTS, but lacks multi-track mixing and sound effects generation
Suno
Excellent for music generation, but not designed for dialogue, sound effects, or all-in-one productions
Descript
A full audio/video editing suite with AI features, but requires manual multi-track assembly
Comparing options? See Seed Audio 1.0 alternatives, scored side by side
Sources
What the review was written against. A verdict with no sources is an opinion.
More AI Generations apps
View all AI Generations
Uni-1 by Luma AI
92Uni-1 is an advanced multimodal text-to-image AI model th...

LTX 2.3 AI Video Generator
91Fast, open-source AI video generator with 4K support, mul...

DemoVexa
90Turn your code into professional product demo videos with AI-generated scripts, animated UI, and natural voiceovers.

tradutor de mangá com IA
88O tradutor de mangá com IA traduz capítulos em lote, personaliza textos e oferece edição visual para estúdios.

OBVELO
88Privacy gateway that masks personal data in LLM traffic

Pixelimg
88A free online AI-powered tool that instantly converts ima...

HeyVid AI
88HeyVid AI is a free all-in-one AI video and image generat...

RestorePhotosApp
88An AI-powered photo restoration app that brings old, blur...

IraVoice
88Private on-device dictation for Apple-silicon Macs.

Mygom SEO
87MygomSEO is an AI marketing agent that audits your site, writes SEO content, publishes to 12+ CMS platforms, posts to social, and monitors rankings 24/7.

pause.do
87A privacy-first browser extension that inserts gentle pau...

DeepSwapAI
87AI face swap online with no subscription, pay per use.
A platform dedicated to providing unbiased reviews of newly launched applications, analyzing everything from their features to their full potential.
info@scoutforge.net© 2026 Scoutforge. All rights reserved.